 Editor's Desk
For 30 years, the world wide web has run on a surprisingly profound social contract: most sites are free for search engines to access, but if you use their content you give credit by linking to the source.
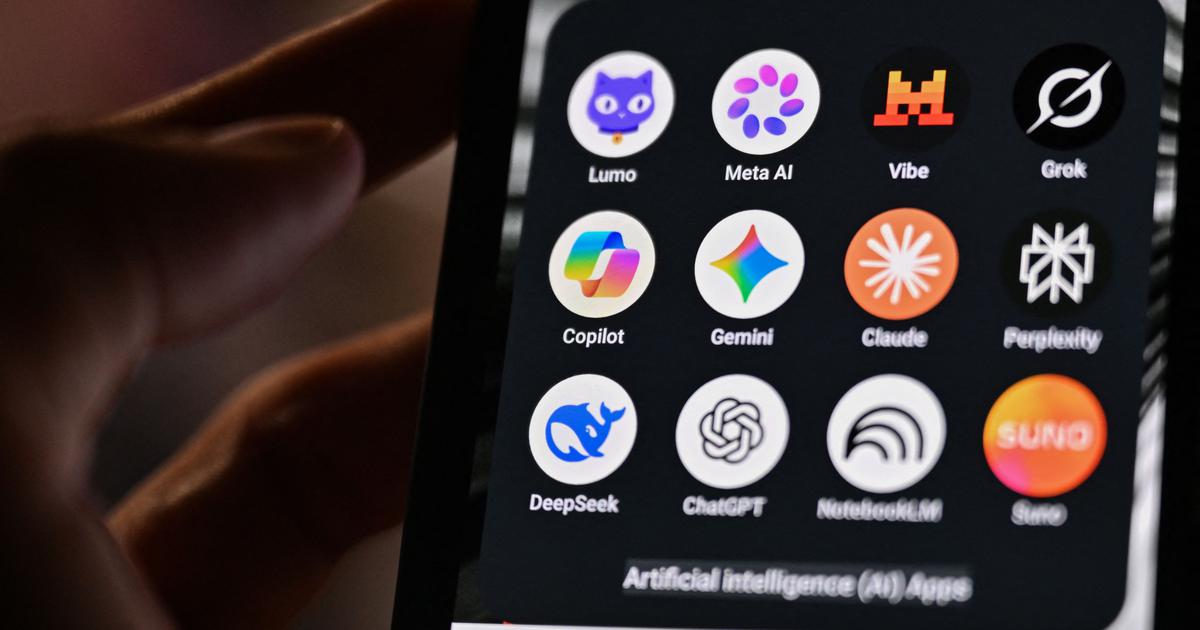
Recently, that social contract has begun to collapse. Artificial intelligence (AI) tools are crawling sites not to link to them, but to train models and generate answers (which may or may not be accurate).
When you search for something, ChatGPT’s response or Google’s AI Overviews may still include links to sources, but they’re a kind of optional extra to the main answer.
This has triggered a bad dynamic for website owners, the public, and even AI companies themselves: as websites lose traffic (and revenue), many are beginning to block AI scraping tools, meaning AI results depend more on low-quality websites (many of which are also generated by AI). As a result, good information can be harder than ever to find.
How we got here
In the early days of the world wide web, search engines and content creators came to an agreement about crawling (the practice of technologically examining a site to index it, so it can be served up in search results). Content creators would provide access to their sites for free, and even allow search engines to reproduce small…
News reported through various sources and compiled with AI. This is automatically generated news content from known, popular, and reliable sources available at the time of publication.
We do not take any responsibility for, nor make any representations regarding, the accuracy, completeness, credibility, or
reliability of the content.
In case of any discrepancy, error, or copyright claim, we will promptly review and remove the content in question where appropriate.
We do not claim ownership of third-party content and assume no responsibility or liability whatsoever for any information contained herein. The credit, links and images are kept intact as an honest gesture, are property of its respective owners.